Empirical Release: Ypru-100M Baseline Validated on NVIDIA H100

Sovereign AI Foundations.
Constant O(1) Memory Architecture.

Yaqgu is an independent research lab engineering foundational sequence models. By mathematically decoupling memory scaling from sequence length, the Ypru foundation series provides unbounded context processing and ultra-fast edge execution with zero KV-cache memory explosions.

Context Memory

424.64 MB

Flat up to infinite tokens

Pre-Training Volume

100,000,000

Permissive tokens streamed

Convergence Delta

-99.1%

Loss: 479.76 → 4.23

Commercial License

Apache 2.0

100% Free commercial use

Empirical Validation

Decoupled Memory vs Sequence Length

Empirical benchmarks comparing standard transformer attention against the Ypru contractive recurrent operator on identical GPU hardware.
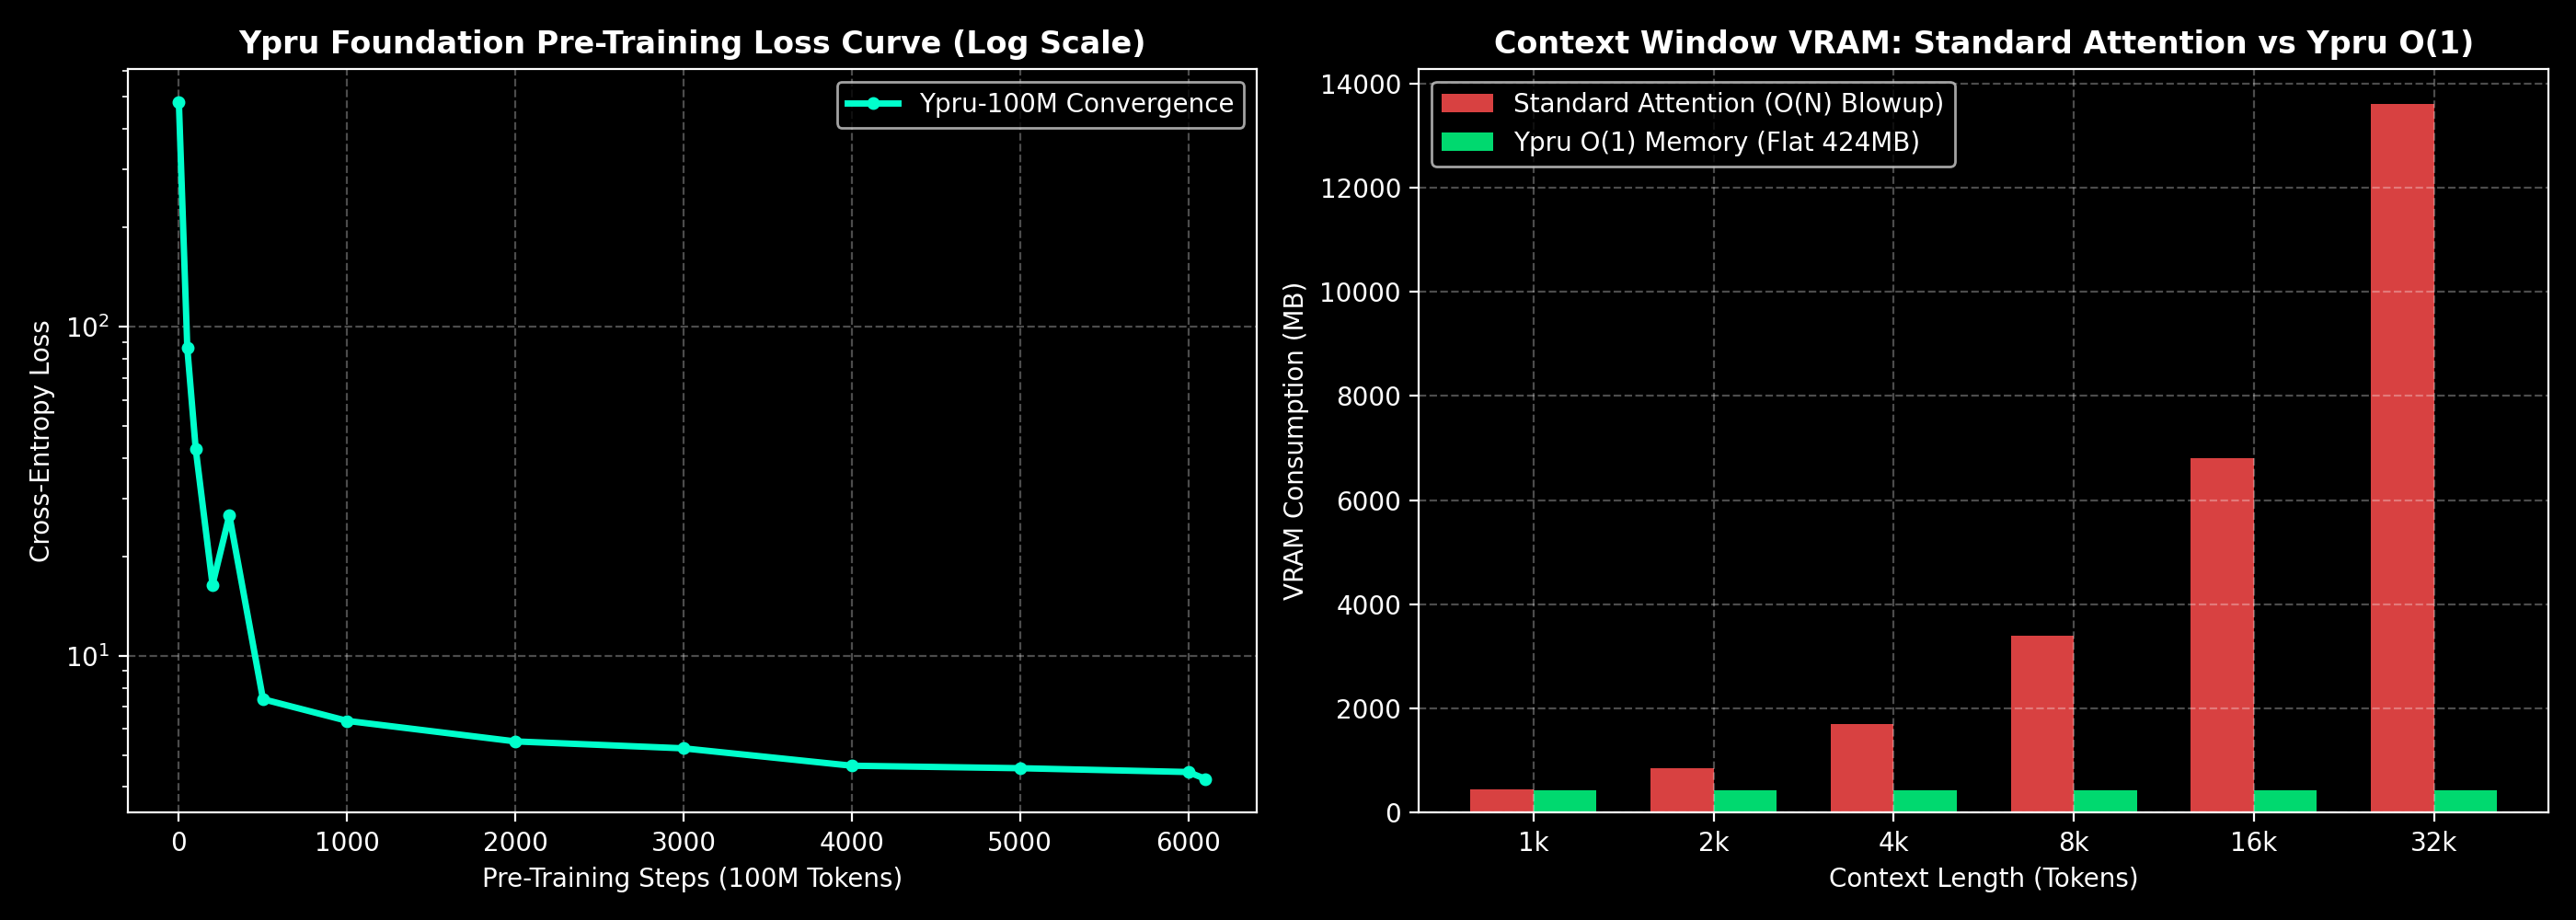
Ypru Pre-training Loss and O(1) Memory Scaling Benchmark
Sequence Context Standard Transformer (LLaMA/Mistral) Ypru Foundation Model Memory Growth Rate
1,024 tokens ~450 MB 424.64 MB 0.00%
4,096 tokens ~1,700 MB 424.64 MB 0.00%
8,192 tokens ~3,400 MB 424.64 MB 0.00%
16,384 tokens ~6,800 MB (OOM on 6GB VRAM) 424.64 MB 0.00%
32,768 tokens ~13,600 MB (OOM on 12GB VRAM) 424.64 MB 0.00%

Licensing Architecture

Apache 2.0 Open Commercial License

Completely permissive, unrestricted commercial rights for enterprise production and developer ecosystems.

100% Free Commercial Rights

Deploy, serve, monetize, and integrate Ypru models in SaaS platforms, edge appliances, internal tools, and commercial products. There are zero revenue thresholds, zero royalties, and zero upfront fees.

Mandatory Attribution Notice

Derivative models, commercial interfaces, and public deployments must simply provide prominent attribution: "Based on Ypru Foundation Architecture by Yaqgu (yaqgu.com)"

Anti-Plagiarism Protection

While derivatives and commercial usage are free, actors cannot rebrand and sell raw unmodified base weights (model.safetensors) as a standalone paid binary without substantial technical contributions.

Integration Specification

Deploy Ypru-100M via Transformers

# Standard integration via Hugging Face AutoModelForCausalLM

from transformers import AutoModelForCausalLM

model = AutoModelForCausalLM.from_pretrained("yaqgu/ypru-100m", trust_remote_code=True)

model.eval()

# Executes with bounded O(1) recurrent state memory

output = model(input_tokens)

Foundational Scale Roadmap

Scaling to Ypru-1.0B

Scaling our contractive recurrence operator across large-scale distributed hardware accelerators.

High-Throughput Distributed Compute

Currently preparing the architecture to pre-train Ypru-1.0B across 20 Billion gold-standard tokens (FineWeb-Edu, Open-Web-Math, and CodeParrot). The resulting weights will be published openly as a foundation benchmark for constant-memory AI.

Strict Data Provenance

Zero web-crawl noise or dubious scraping. 100% legally and commercially permissive corpora filtered strictly for educational density, algorithmic execution traces, and causal reasoning representations.